SEC.01 / AI Tools & Prompts
SHA Pinning Did Not Save the Plugin Install
Air Security's Plugin4Shell hits Claude Code, Codex, Copilot, and Gemini CLI. Two vendors patched. Copilot is disputed. AI commits still leak secrets at 2x.
Air Security's Plugin4Shell hits Claude Code, Codex, Copilot, and Gemini CLI. Two vendors patched. Copilot is disputed. AI commits still leak secrets at 2x.
Open-weight models now handle most tokens on gateways like Vercel's and OpenRouter, yet closed models still take about 86% of estimated spend. What the September 2026 data shows, why Chinese open models lead, and how a 9B longevity model topped frontier systems on a domain benchmark.
After fans flagged suspected AI imagery in its VISION 2026 II showcase, Level-5 apologised, explained which flaws were human error and pledged to avoid direct AI use in videos for fans. A summary of the statement, the contrasting Higgsfield Adathon win, and practical disclosure lessons.
Plugin4Shell let attackers bypass SHA-pinned plugins in Claude Code, Codex, Copilot and Gemini CLI. Which versions fix it, how Claude Code Projects now runs parallel cloud sessions, what Safari 27's MCP server exposes, and a practical security checklist for coding agents.
A Nature paper describes Paper2Agent, which converts a research paper and its code into an MCP server that a chat agent can use. How it works, the AlphaGenome case built in about 45 minutes for US$14, accuracy results, limits, and how researchers can use it.
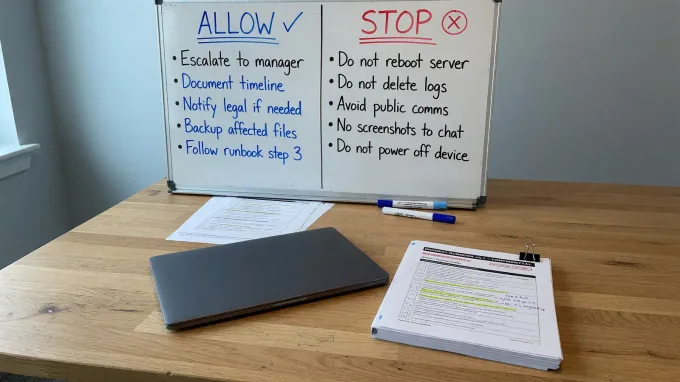
As reports of AI agents misbehaving in lab tests grow, CIOs are building guardrails around agents already in production. What Cisco, Intuit, Workday and AT&T are doing, what Deloitte's survey shows about adoption, and a practical guardrail checklist.
Many AI image apps resell the same underlying models, including Google's Nano Banana. A guide to comparing platforms like Adobe Firefly and Kling on credits, controls and licensing, what Lifehacker found comparing ChatGPT Images 2.5 with Nano Banana 2, and the privacy questions to ask before uploading photos.
Demis Hassabis proposed training an AI only on pre-1911 knowledge to see if it could derive general relativity. What experiments with vintage models and world-model probes have found, why AI math results such as GPT-6 Astra's are a different kind of claim, and how to evaluate AI discovery.
Cognition released SWE-2, a coding model post-trained from Kimi K3, two days after raising $2 billion at a $48 billion valuation. Benchmarks against GPT-6 Astra and Fable 5.1, what is included in Devin's $20 Pro plan, and how to evaluate it.
Gartner expects 40% of enterprise apps to include task-specific AI agents by the end of 2026. PagerDuty's CIO argues the job is now deciding where agents act alone, where they need review and where they are kept out. A practical autonomy framework.
OpenAI's Images 2.5 cuts generation latency by up to 50% and keeps edits more consistent across turns. What changed from Images 2, how to use it for character-consistent series, how it compares with a Nano Banana pipeline, and what the API models cost.
Inception's Mercury 2.5 diffusion LLM generates 1,107 tokens per second with a 260K context window at $0.20/$0.75 per million tokens. How diffusion language models differ, where Mercury is used, what the company-reported numbers mean, and how to test it. Updated with Mercury 3.