SEC.03 / LLM Research
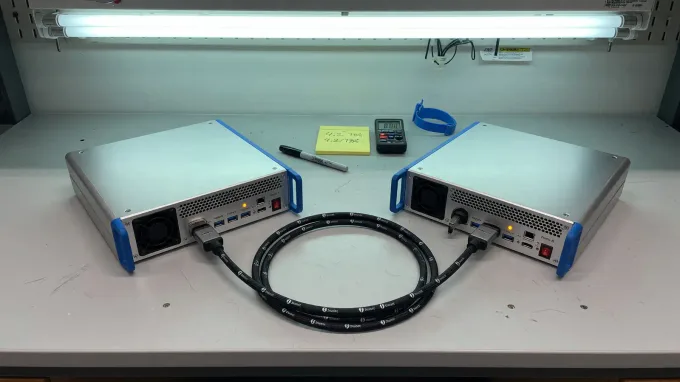
Apple MLX Runs a Large Open Model on Four Mac Studios at 36 Tokens/s: When a Desk Cluster Makes Sense
Apple's MLX team ran Meta's Muse Spark Open on four Mac Studios at more than 36 tokens per second. The memory math, how the Thunderbolt 5 RDMA pipeline works, its limits, and when a desk-sized Mac cluster makes sense.